Fix Qwen image editing artifacts with a safe studio grid workflow.
LLST: benchmark local LLMs on quality and speed, not just tokens per second.
Audit agent skills and trim context bloat with Skill Context Doctor.
Comprehensive guide to deploying Qwen 3.8 27B Uncensored on Apple Silicon Mac with oMLX, achieving 70+ tok/s single-stream and 240+ tok/s continuous batching.
Deploy Bonsai 2 27B PQ2_0 on an RTX 3060 12GB with PrismML, a local OpenAI-compatible API, systemd service, and safe LAN access.
Can a 7.2GB 27B model handle real code-agent work? A controlled Bonsai 2 PQ2_0 versus Qwen3.8 benchmark of capability and convergence.
Benchmark & deployment guide for Qwen 3.8 125B on dual AMD RX 7900 XTX (48GB VRAM). 38 tok/s daily API & 28 tok/s at 48K context with ROCm 7.14.
A hands-on guide to transforming spare PCs into dedicated local LLM inference servers with AI Linux: zero-command auto-installer, hardware detection, and llama.cpp.
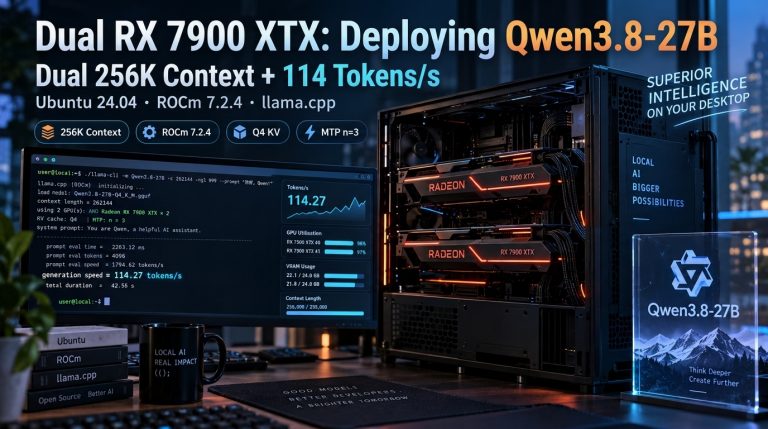
How to deploy Qwen3.8-27B across dual AMD Radeon RX 7900 XTX 24GB GPUs on Ubuntu 24.04 with 48GB host RAM: achieving two fully independent 256K context windows, 114.45 Tokens/s aggregate decode throughput, and minimal cross-load interference for multi-agent workflows. Complete with ROCm 7.2.4 setup, MTP step tuning, and dual-client integration.
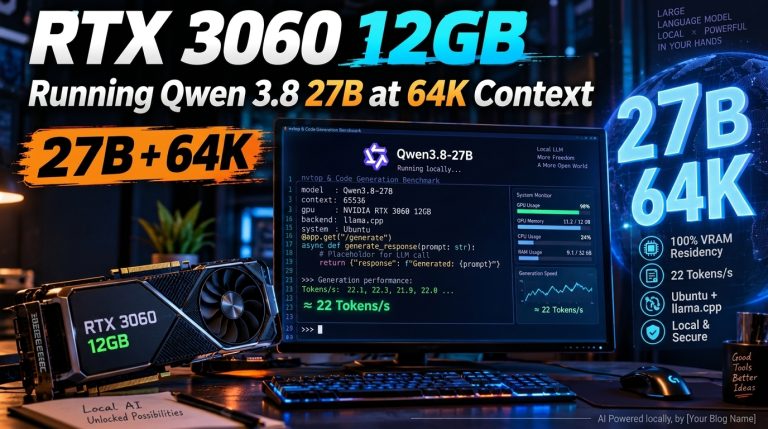
Single Source of Truth (SSOT) Statement: All benchmark metrics, VRAM allocations, and long-context stress tests in this guide were conducted on September 13,…
Free AI Quota & Service Radar by Web Studio. Get OpenAI Codex reset forecasts, Claude limit health, Cursor quota tracking, and DeepSeek daily 50% off window alerts in your local timezone.
A beginner-friendly guide to choosing the right local LLM for your PC and Mac. Compare Qwen vs DeepSeek, size your VRAM and unified memory, and avoid common beginner traps.