Can an entry-level 12GB RTX 3060 run a 125B AI model? We tested Qwen3.8 Flash Next on an old $420 Xeon E5 X99 rig with 96GB DDR3 RAM, reaching up to 73.69 tokens/sec decode throughput. Complete benchmarks, memory hierarchy, and 5-step Strata tuning playbook.
Executive Summary & Quick Takeaways: - Core Achievement: Yes, an NVIDIA GeForce RTX 3060 (12GB VRAM) can run a 125-billion-parameter MoE model locally. I…
Bare-metal benchmark and 4-step guide for running Qwen3.8-Flash-Next 125B (IQ3_S) on a 10GB RTX 3080 + 96GB DDR4 RAM with Speedy: 94.6 tok/s peak, 87.2 tok/s at 200K context, and +26.0% cold prefill gain from PCIe 4.0 x16.
From hardware prep to engine builds and dual-GPU config, reproduce the 125B RX 7900 XTX deployment with 256K context.
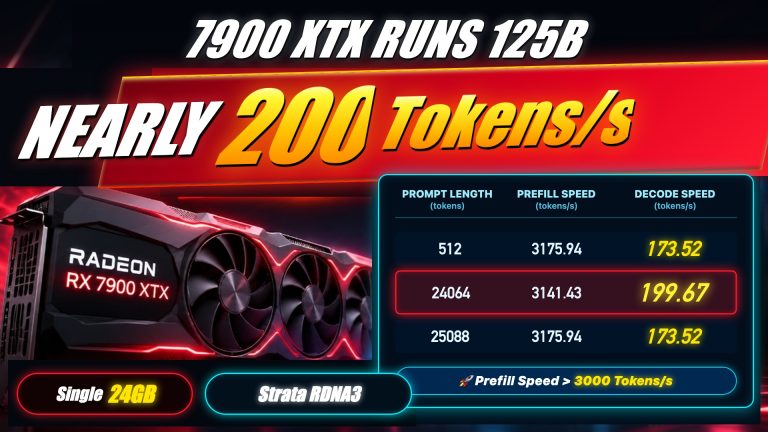
Run a 125B MoE at 200 tokens/s on a single 24GB RX 7900 XTX: the complete Strata benchmark guide.
Fit a 125B MoE on a 12GB RTX 3060 with Strata three-tier storage: config, tuning, and real numbers.
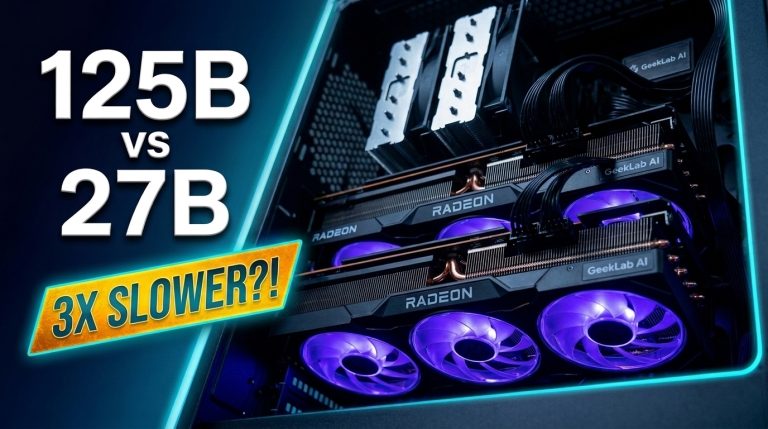
125B MoE vs 27B dense on dual RX 7900 XTX: the 3x speed trap, verified with real code benchmarks.
Coding benchmarks on dual RX 7900 XTX: when the bigger model is not the faster choice.
Run a 90GB MoE on a single 24GB GPU: Strata plus RX 7900 XTX with 128K context.
Tune an 84GB Qwen3.8-Flash-Next to 1,320 tok/s prefill on a single RX 7900 XTX.
Make a local Bonsai 27B agent finish what it starts: a convergence tuning guide.
From storyboard to a 32.8-second clip: a local AI video workflow with Qwen and MiniMax.