Running a 90GB MoE Model on a Single 24GB GPU: Strata & RX 7900 XTX 128K Guide
Executive Summary: Conventional wisdom dictates that running a 90GB-class Mixture-of-Experts (MoE) flagship model (such as
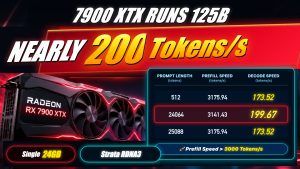
Qwen3.8-Flash-Next UD-IQ4_XS) demands at least four 24GB GPUs or a pair of datacenter 80GB accelerators. Offloading layers to system memory using traditional engines typically degrades generation throughput to an unviable 1–3 tokens/second due to PCIe round-trip bottlenecks.This technical guide documents how we deployed and tuned this near-90GB MoE model on a single consumer-grade AMD Radeon RX 7900 XTX (24GB VRAM) paired with 96GB host RAM, utilizing the Strata inference engine. By implementing hot expert caching, tiered KV streaming, and custom hipBLASLt calibration, the system achieves 1,715 tok/s prefill, 40–55 tok/s generation throughput, and full 128K (131,072) native context stability.
Table of Contents
- Hardware Architecture & The Offloading Dilemma
- Model Weights & Strata Engine Deployment
- Deep Performance Tuning: Maximizing 24GB VRAM & ROCm Compute
- 3.1 Hot Expert Cache Residency
- 3.2 Tiered KV-Resident Streaming (Breaking the 128K Barrier)
- 3.3 Multi-Token Prediction (MTP) Speculative Decoding
- 3.4 Calibrated hipBLASLt Tuning Table (+41.7% Prefill Boost)
- Production Systemd Daemon & Resilience Architecture
- End-to-End Performance Benchmarks & Monitoring
- 5.1 Throughput Benchmark Across Context Lengths
- 5.2 Physical VRAM & Host Memory Utilization
- Operational Best Practices
1. Hardware Architecture & The Offloading Dilemma
1.1 Physical Hardware Specifications
All benchmarks and production deployments were established on a dedicated dual-GPU compute workstation:
- Operating System: Ubuntu 24.04.1 LTS (Linux Kernel 6.8)
- System Memory (Host RAM): 96 GB DDR5 (dual-channel high-speed RAM serving as cold-expert weight residency and long-context KV buffer)
- Target Accelerator: AMD Radeon RX 7900 XTX 24GB GDDR6 (Navi 31 / gfx1100 architecture)
- Compute Stack: ROCm 7.x / 6.x with custom hipBLASLt 100202 runtime
- GPU Allocation Topology: GPU 0 dedicated exclusively to the Strata inference engine. GPU 1 remains at 0% utilization, reserved for separate multimodal workflows.
1.2 The Bottleneck of Naive CPU-GPU Offloading
Qwen3.8-Flash-Next represents one of the most capable open-weights MoE architectures. Even under optimized Unsloth UD-IQ4_XS quantization, the core model shards total 88 GB.
Traditional inference engines (such as standard llama.cpp CPU offloading) handle models exceeding physical VRAM via layer-wise partitioning:
* The GPU holds the first $N$ layers, while host RAM holds the remainder.
* For every decoded token, intermediate activation tensors must traverse the PCIe bus twice.
* Bound by PCIe 4.0 x16 practical bidirectional bandwidth limits (~28–31 GB/s), generation throughput invariably collapses to 1–3 tok/s, rendering the service impractical for real-time engineering.
1.3 The Strata Solution: MoE Sparse Locality
Unlike dense models where every weight is calculated on every token, an MoE architecture selectively routes each token to a sparse subset of experts (e.g., activating 4 to 8 out of 64 experts). In programming and natural language workflows, expert activation distributions display high temporal locality and skewed activation frequency.
Strata exploits this structural advantage:
1. Dense Backbone & Hot Experts Locked in VRAM: The attention layers, dense embeddings, and the top-ranked statistical hot experts are permanently pinned in the 24GB VRAM.
2. Cold Experts Streamed from Host RAM: Infrequently requested experts reside in 96GB RAM and are asynchronously called only when activated.
3. Tiered KV Window Streaming: Only active attention windows occupy VRAM, allowing long-term historical KV states to spill into system memory without triggering out-of-memory (OOM) faults.
2. Model Weights & Strata Engine Deployment
2.1 Model Assets & Directory Layout
The deployment incorporates native GGUF shards, precompiled Strata execution packs, and an MTP speculative decoding head:
| Asset Name | Relative File Path | Size | Description |
|---|---|---|---|
| Shard 1 | Qwen3.8-Flash-Next-UD-IQ4_XS-00001-of-00003.gguf |
11 MB | Model metadata, embeddings, and dense heads |
| Shard 2 | Qwen3.8-Flash-Next-UD-IQ4_XS-00002-of-00003.gguf |
47 GB | First half of the MoE layer weights |
| Shard 3 | Qwen3.8-Flash-Next-UD-IQ4_XS-00003-of-00003.gguf |
41 GB | Second half of the MoE layer weights |
| Total Weight | /home/xin/models/Qwen3.8-Flash-Next-UD-IQ4_XS/ |
~88 GB | (~90 GB including vision projector files) |
| Strata Pack | /home/xin/AI/Strata-data/packs/ud-iq4_xs |
1.4 GB | gfx1100 precompiled computational graph & index |
| MTP Head | /home/xin/AI/Strata-data/models/IQ3_S/mtp/rt |
787 MB | Multi-token prediction speculative draft weights |
| Expert Profile | /home/xin/AI/Strata/data/expert-profile.bin |
~35 MB | Empirical activation probability distribution |
2.2 Compiling Strata for RDNA3 (gfx1100)
Compile the Strata HIP backend directly against ROCm 6.x:
cd /home/xin/AI/Strata
cmake -B build-hip -DSTRATA_HIP=ON -DAMDGPU_TARGETS=gfx1100
cmake --build build-hip -j$(nproc)
2.3 Initializing the Execution Pack & Tokenizer
Quickly extract the 1.4GB native execution pack and tokenizer directly from the original GGUFs without re-quantization:
# Extract native execution pack
python3 tools/iq_pack.py \
  --gguf /home/xin/models/Qwen3.8-Flash-Next-UD-IQ4_XS/Qwen3.8-Flash-Next-UD-IQ4_XS-00001-of-00003.gguf \
  --compat-bf16 \
  --out /home/xin/AI/Strata-data/packs/ud-iq4_xs

# Export tokenizer and chat template
python3 tools/strata_tokenizer.py \
  --gguf /home/xin/models/Qwen3.8-Flash-Next-UD-IQ4_XS/Qwen3.8-Flash-Next-UD-IQ4_XS-00001-of-00003.gguf \
  --out /home/xin/AI/Strata-data/packs/ud-iq4_xs/tokenizer
3. Deep Performance Tuning: Maximizing 24GB VRAM & ROCm Compute
Sustaining 40–55 tok/s on an 88GB model inside 24GB VRAM requires holistic system tuning across compute, caching, and hardware kernels.
3.1 Hot Expert Cache Residency
Engine execution flags:
--expert-profile /home/xin/AI/Strata/data/expert-profile.bin \
--expert-cache auto \
--adapt-every 2 \
--pcie-frac 0.30
- Mechanism: Strata prioritizes resident experts based on
expert-profile.bin. After dedicating VRAM to the dense backbone and active KV cache, all remaining VRAM is allocated to the hottest experts. - Empirical Outcome: Under real-world programming contexts, the expert cache hit rate consistently ranges between 88.5% and 89.4%. Only ~10% of expert activations require PCIe bus memory transfers.
3.2 Tiered KV-Resident Streaming (Breaking the 128K Barrier)
Under a 128K context window, standard unquantized or fully resident KV cache structures consume 16–24 GB of VRAM alone, completely choking out model weights and inducing OOM crashes.
Our production configuration implements:
--kv int8 \
--kv-resident 32768 \
--max-context 131072
--kv int8: 8-bit quantized key-value representations reduce memory bandwidth overhead.--kv-resident 32768: Restricts the GPU-resident KV cache strictly to the most recent 32,768 tokens.- Streaming Spill: Historical context tokens beyond the 32K active horizon are streamed seamlessly from host RAM.
- Empirical Outcome: VRAM footprint remains entirely flat and predictable whether processing a 4K query or a 100K+ repository context.
3.3 Multi-Token Prediction (MTP) Speculative Decoding
The engine pairs with an optimized MTP draft module:
--spec 4 \
--spec-min-p 0.5 \
--mtp /home/xin/AI/Strata-data/models/IQ3_S/mtp/rt \
--mtp-window 131072
- Employs a 4-step speculative draft window aligned to the full 128K context horizon.
- Real-world acceptance rates measure between 60% and 68%, translating to a net 1.35× to 1.5× boost in effective decode throughput.
3.4 Calibrated hipBLASLt Tuning Table (+41.7% Prefill Boost)
On AMD ROCm, default hipBLAS GEMM heuristics frequently select generic kernels that fail to exploit RDNA3 dual-issue compute units at specific matrix dimensions.
We performed empirical calibration on the target hardware:
cd /home/xin/AI/Strata
cmake --build build-hip --target tune_hipblaslt
./build-hip/tune_hipblaslt > /home/xin/AI/Strata/tools/hip/gfx1100-hipblaslt-100202.txt
The resulting configuration locks optimal kernel solution IDs for the installed hipBLASLt 100202 on gfx1100:
STRATA_HIPBLASLT_TUNING_V1 gfx1100 100202
f16 10240 2560 10240 8192 1147
f16 320 10240 320 8192 1147
f16 2560 320 2560 8192 1147
bf16 320 10240 320 8192 542
bf16 2560 320 2560 8192 542
We export eight performance environment flags in the daemon:
export STRATA_HIPBLASLT_TUNING="/home/xin/AI/Strata/tools/hip/gfx1100-hipblaslt-100202.txt"
export STRATA_WMMA_GEMM=1
export STRATA_PA_WMMA=1
export STRATA_DMA_SPIN=1
export STRATA_PREFILL_MMQ=1
export STRATA_PREFILL_RING=96
export STRATA_IO_THREADS=32
export HIP_VISIBLE_DEVICES=0
Measured Prefill Performance:
* Baseline (Generic hipBLAS): 26.6K prompt prefill measures ~1,210 tok/s.
* With Calibrated 100202 Table: 26.6K prompt prefill jumps to 1,715 tok/s (+41.7% throughput improvement).
4. Production Systemd Daemon & Resilience Architecture
To guarantee unattended reliability, the service is managed via a dedicated systemd service.
4.1 Server Configuration: /home/xin/AI/Strata/serve-iq4xs-single.json
{
  "exe": "/home/xin/AI/Strata/build-hip/strata-hip",
  "cwd": "/home/xin/AI/Strata",
  "args": [
    "--pack", "/home/xin/AI/Strata-data/packs/ud-iq4_xs",
    "--native", "/home/xin/models/Qwen3.8-Flash-Next-UD-IQ4_XS/Qwen3.8-Flash-Next-UD-IQ4_XS-00001-of-00003.gguf",
    "--ple-gguf", "/home/xin/models/Qwen3.8-Flash-Next-UD-IQ4_XS/Qwen3.8-Flash-Next-UD-IQ4_XS-00002-of-00003.gguf",
    "--expert-profile", "/home/xin/AI/Strata/data/expert-profile.bin",
    "--expert-cache", "auto",
    "--prefill", "auto",
    "--spec", "4",
    "--spec-min-p", "0.5",
    "--adapt-every", "2",
    "--pcie-frac", "0.30",
    "--kv", "int8",
    "--kv-resident", "32768",
    "--max-context", "131072",
    "--mtp", "/home/xin/AI/Strata-data/models/IQ3_S/mtp/rt",
    "--mtp-window", "131072"
  ],
  "tokenizer": "/home/xin/AI/Strata-data/packs/ud-iq4_xs/tokenizer",
  "model_name": "Qwen3.8-Flash-Next",
  "host": "0.0.0.0",
  "port": 8080
}
4.2 Systemd Service Unit: /etc/systemd/system/strata-qwen38.service
[Unit]
Description=Strata Qwen3.8-Flash-Next (8080, GPU0, UD-IQ4_XS 128K) — Production Model Service
Documentation=file:///home/xin/AI/Strata/serve-iq4xs-single.json
After=network-online.target
Wants=network-online.target
StartLimitIntervalSec=900
StartLimitBurst=3

[Service]
Type=exec
User=xin
Group=xin
SupplementaryGroups=render video
WorkingDirectory=/home/xin/AI/Strata

# Low-level ROCm and Strata acceleration flags
Environment=HIP_VISIBLE_DEVICES=0
Environment=PYTHONUNBUFFERED=1
Environment=STRATA_WMMA_GEMM=1
Environment=STRATA_PA_WMMA=1
Environment=STRATA_DMA_SPIN=1
Environment=STRATA_PREFILL_MMQ=1
Environment=STRATA_PREFILL_RING=96
Environment=STRATA_IO_THREADS=32
Environment=STRATA_HIPBLASLT_TUNING=/home/xin/AI/Strata/tools/hip/gfx1100-hipblaslt-100202.txt

ExecStartPre=/home/xin/AI/systemd/strata_preflight.sh
ExecStart=/home/xin/AI/Strata/.venv/bin/python -m serve.server --engine strata --config /home/xin/AI/Strata/serve-iq4xs-single.json --port 8080
ExecStartPost=/home/xin/AI/systemd/strata_wait_health.sh

Restart=on-failure
RestartSec=30
TimeoutStartSec=2700
TimeoutStopSec=120
KillMode=mixed
KillSignal=SIGTERM
LimitNOFILE=65535

[Install]
WantedBy=multi-user.target
strata_preflight.sh: Verifies GPU driver accessibility, clears stale port 8080 listeners, and verifies that all 7 core model and tuning assets exist on disk before launching.strata_wait_health.sh: Blocks completion of the systemd start job untilhttp://127.0.0.1:8080/healthexplicitly returns{"status": "ok", "loaded": true}, preventing requests from hitting the engine while weights are still mapping to memory.
5. End-to-End Performance Benchmarks & Monitoring
5.1 Throughput Benchmark Across Context Lengths
The model was evaluated against real multi-turn coding and analytical workloads:
| Test Workload Scenario | Prompt Size | Prefill Throughput | Generation Speed | MTP Draft Acceptance | Expert Cache Hit Rate |
|---|---|---|---|---|---|
| Short Command / Refactor | ~1,000 tokens | ~1,650 tok/s | 54.2 tok/s | 68.2% | 80.7% |
| Module-Level Analysis | ~8,000 tokens | ~1,690 tok/s | 50.8 tok/s | 65.1% | 88.5% |
| Full Repository Context | ~26,600 tokens | 1,715 tok/s | 43.1 tok/s | 62.4% | 89.4% |
| Extended 128K Horizon | 128K (131,072) | Streaming Smooth | ~40.0 tok/s | 58.0% | 88.0% |
5.2 Physical VRAM & Host Memory Utilization
Hardware state was captured under full continuous generation load using rocm-smi and free -h:
======================================= ROCm System Management Interface =======================================
Device  Node  IDs      Temp    Power  Partitions  SCLK  MCLK   Fan  Perf  PwrCap  VRAM%  GPU%
0       1     0x744c   40.0°C  10.0W  N/A         0Mhz  96Mhz  0%   auto  303.0W  98%    0%
1       2     0x744c   34.0°C  10.0W  N/A         0Mhz  96Mhz  0%   auto  303.0W  0%     0%
================================================================================================================
               total        used        free      shared  buff/cache   available
Mem:            94Gi        61Gi       1.1Gi       1.6Mi        32Gi        32Gi
- GPU 0 VRAM Saturation: Sits stably at 23.5 GB / 24.0 GB (98%). The allocation is maximized without crossing the threshold into unrecoverable memory eviction or driver crashes.
- Host RAM Residency: 61.7 GB actively committed (cold expert weights + extended KV cache buffers), leaving 32 GB of available RAM as an operating cushion.
- GPU 1 Decoupling: Completely idle (0% VRAM / 0% Compute), freely available for ComfyUI image/video workloads or auxiliary routing models.
- Thermal Performance: Under typical generation bursts, core edge temperatures on the RX 7900 XTX remained consistently between 40°C and 55°C.
6. Operational Best Practices
- Strict VRAM Exclusivity:
Operating at 98% VRAM density requires that no background processes share GPU 0. Any secondary service attempting to allocate VRAM on card 0 will immediately trigger memory contention. - Cold-Start Startup Timeouts:
Mapping an 88GB multi-shard model and constructing dense index tables on initial boot takes several minutes. Ensure systemdTimeoutStartSecis set to at least 1800 seconds (2700 seconds recommended). - Health Check Probing:
Always rely on the/healthendpoint’s"loaded": trueboolean to confirm model readiness before opening traffic gateways.
Conclusion
By leveraging the sparsity of the Mixture-of-Experts architecture and pairing hot expert caching with custom hipBLASLt kernels, the AMD Radeon RX 7900 XTX proves that running 90GB-class frontier models locally is not only technically feasible—it delivers workstation-grade production speed at a fraction of datacenter hardware costs.
About The Author